Script Development / Connector Subscription
Some Connectors support message subscription, and DataFlux Func provides a unified way to subscribe.
In earlier versions, this was called 'Data Source'; the current version has changed it to 'Connector'
1. Introduction
Due to the Script execution mechanism of DataFlux Func, a function must eventually end after it is started; infinite function execution is not allowed.
Therefore, for long-running processing such as subscription, directly writing a long-running consumer in DataFlux Func is not supported.
Instead, you need to specify the subscription topic in the Connector, and the DataFlux Func main program is responsible for subscribing to messages.
When the DataFlux Func main program receives a message, it forwards the message to the specified message handler function for processing, thereby completing the subscription message processing.
2. Connectors Supporting Subscription
The latest version of DataFlux Func supports subscription to the following Connectors
3. Operation Steps
Taking subscribing to and processing Redis messages as an example, the specific operation steps are as follows:
3.1 Writing the Message Handler Function
The message handler function has a fixed function form, for example:
| Python | |
|---|---|
1 2 3 4 | |
After completing the Script, save and publish it:
3.2 Creating and Configuring the Connector
In addition to filling in the basic configuration, you also need to fill in the subscription Topic and the corresponding handler function.
The handler function is the message_handler(...) function written above:
3.3 Publishing a Message and Confirming Message Processing
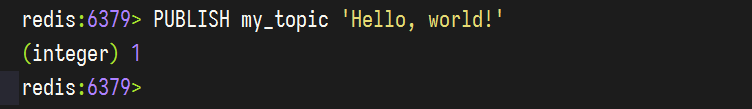
When the publisher publishes a message as shown below, the message will be forwarded by the DataFlux Func main program to the above message_handler(...) function for processing:
On the Connector configuration page, the latest consumption information will appear below the corresponding topic:
After clicking, you can see more detailed task information:
At this point, you can confirm that the message published in Redis is indeed received and processed by the message_handler(...) function.
4. Publishing Messages
Connectors that support message subscription generally also support publishing messages.
For publishing messages, see the API of the corresponding Connector Object in Script Development / Connector Objects with DFF.CONN, which is generally in the form of .publish(topic, message).
5. Task Records of the Message Handler Function
In the latest version of DataFlux Func, you can directly view the task records of the message handler function.
If the number of subscribed messages is huge, recording the processing log of each message may itself cause performance issues. You can refer to Deployment and Maintenance / System Metrics and Task Records / Disable Local Function Task Records to disable 'Local Function Task Records' and reduce MySQL storage pressure
In the old version of DataFlux Func, the message handler function does not support querying task records. If you want to record errors that occur during processing, you can write the relevant information to DFF.CACHE in the message handler function.
Refer to the following code implementation:
| Python | |
|---|---|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 | |
When an issue occurs during execution, you can view the detailed information in "Management / Function Cache Manager".
6. Single Subscription and Multiple Subscription
Added in version 1.7.31
All subscribers run in the server service of DataFlux Func. After a subscriber receives a message, it generates a function execution task based on the configuration and sends it to worker for execution.
Subscribers support 2 subscription modes:
- Single subscription: No matter how many
serverreplicas are started, the subscriber will only run in one of theserverinstances. - Multiple subscription: When multiple
serverreplicas are started, the subscriber will run in everyserver.
For Redis subscribers, since shared subscription processing is not supported, multiple subscription will only lead to duplicate message consumption, so only single subscription is currently supported.
For MQTT and Kafka subscribers, you can choose either single subscription or multiple subscription.
When MQTT uses multiple subscriptions, the Topic must be subscribed in a shared subscription manner according to $share/group_name/topic_name; otherwise, duplicate messages will be received.
For information about the services included in DataFlux Func and starting multiple server replicas, please refer to Deployment and Maintenance / Architecture, Scaling and Resource Limits
7. Improving Subscription Processing Speed
Added in version 1.7.31
For DataFlux Func, since subscribers run in the server service while functions run in the worker service, the subscription processing speed consists of two parts: the speed of receiving subscribed messages and the execution speed of subscription functions.
If the number of subscribed messages is not large, but each message is complex and time-consuming to process, you need to increase the number of worker instances to ensure timely message processing.
If the number of subscribed messages is huge, you need to increase the number of both server and worker instances and set the subscriber to "Multiple Subscription" mode.
For information on how to scale the system, please refer to Deployment and Maintenance / Architecture, Scaling and Resource Limits
8. Subscription Limits
Added in version 1.7.31
When the number of subscribed messages is huge, due to different server-side publish-subscribe methods, there are correspondingly different limits.
Redis / MQTT
Redis and MQTT subscribers cannot control the message reception speed on the subscribing side, so the received messages enter an internal buffer pool.
The default size of the buffer pool is 5000, meaning at most 5000 subscribed messages are allowed to reside and wait for processing. If more messages are received during this period, the overflow messages will be discarded.
To solve the above problem, you can increase the number of worker instances to improve the processing speed of subscribed messages.
Kafka
Since Kafka subscribers can control the message reception speed on the subscribing side, there is no buffer pool and no messages will be discarded.
When the message processing speed cannot keep up with the message publishing speed, you can increase the number of worker instances to improve the processing speed of subscribed messages.
9. Known Issues
The currently known issues are as follows.
MQTT Lag or Failure to Receive Messages
When an MQTT Broker connects to EMQX, it may experience lag or fail to receive messages.
This issue has been observed in early community standalone versions of EMQX; other versions of EMQX have not been tested yet.
However, this issue has not been observed when connecting to mosquitto.
Kafka Cannot Consume Immediately After Startup
After subscribing, the Kafka Connector may remain in a paused state for the first few minutes before it proceeds to consume messages normally.
The cause may be related to Kafka's Rebalance mechanism.